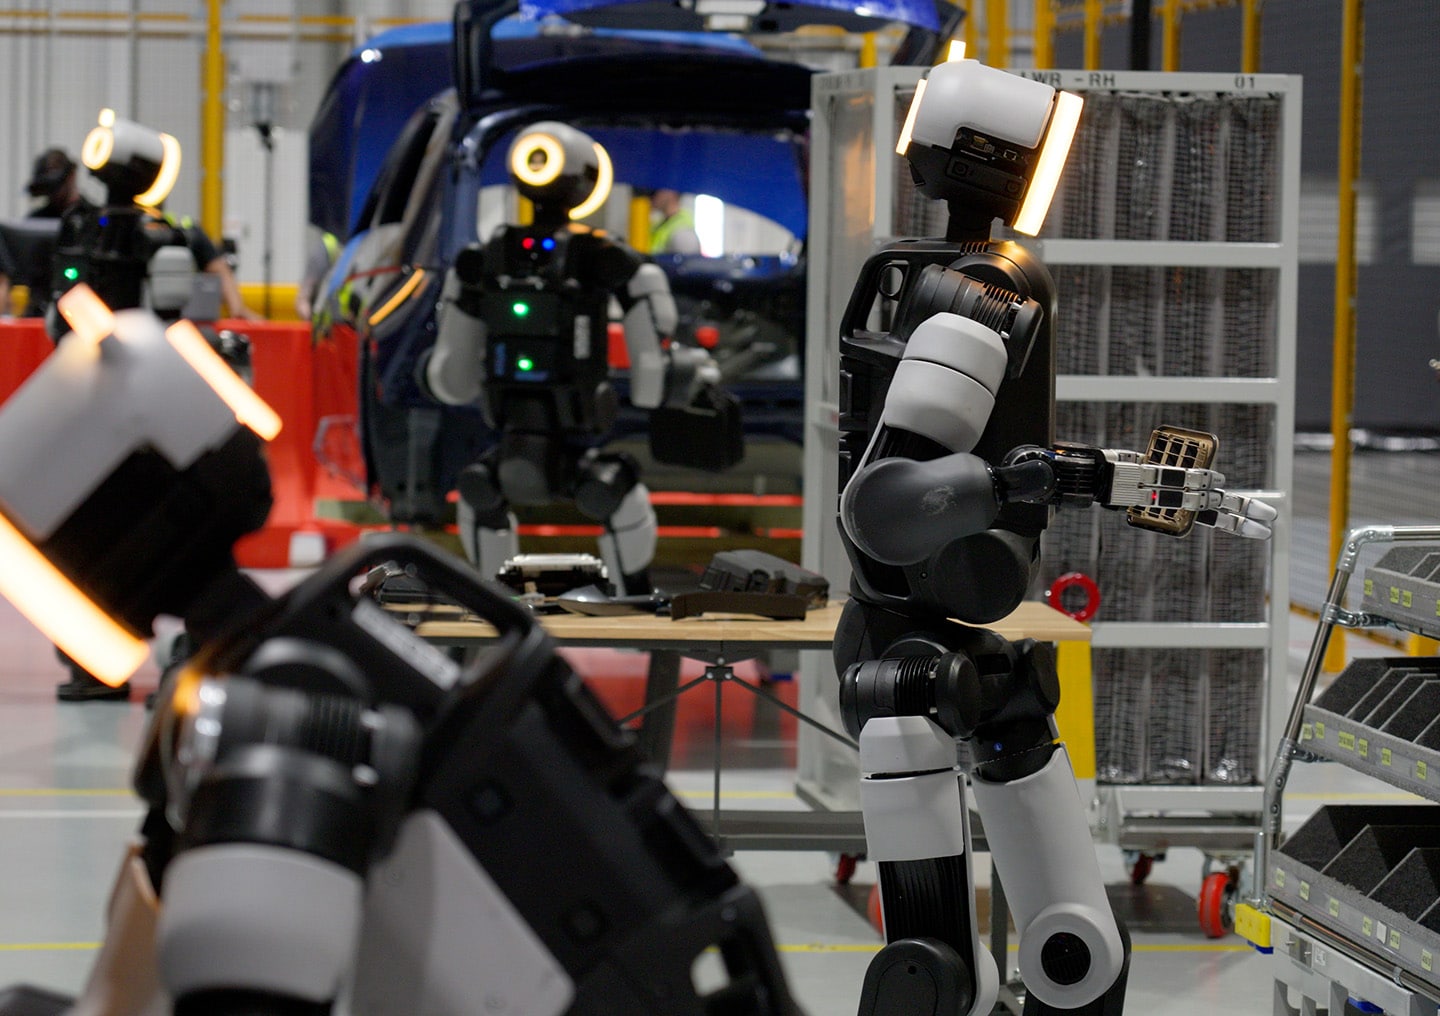
Inside OriginFlow's Bet on Muscle-Signal Robot Data
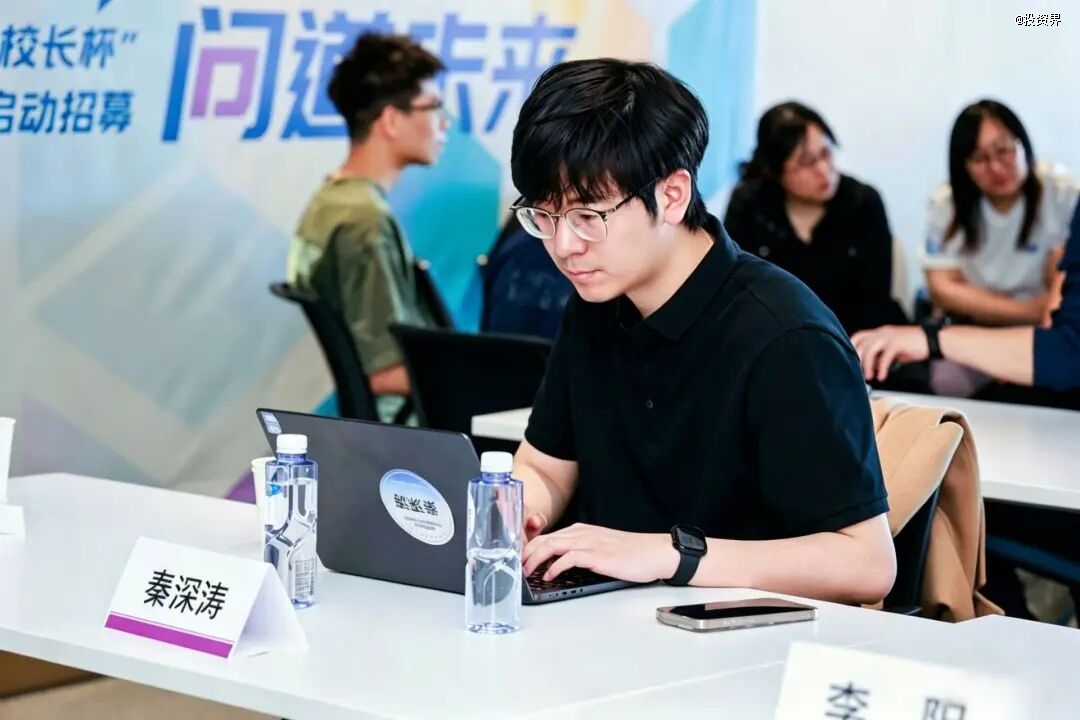
Tsinghua PhD candidate Qin Shentao's year-old start-up OriginFlow has raised over US$69 million behind NeuroScale, a wristband-based system that reads muscle signals to capture the force and contact data embodied AI needs, packaged as transferable Human Tokens.

The Bottleneck Nobody Wants to Admit Is the Real One
Every embodied-AI company chasing a general-purpose robot arm is, underneath the marketing, chasing the same scarce resource: enough recorded examples of a human hand doing a task precisely, repeatably, and in a format a model can actually learn from. Teleoperation rigs are slow and expensive to run at scale. Motion-capture suits track position but miss the force and contact information that determines whether a grip actually holds. Video alone, the cheapest and most abundant data source available, cannot tell a model how hard a hand is pressing or when a fingertip has slipped, the exact information a robot needs to manipulate anything more delicate than a rigid block. OriginFlow, a Beijing-founded start-up barely a year old, has raised more than RMB 500 million (approximately US$69 million) on the argument that this data gap, not model architecture, is the binding constraint on how fast humanoid and robotic-arm manipulation actually improves.
OriginFlow was founded in August 2025 by Qin Shentao, a 25-year-old doctoral candidate in Tsinghua University's School of Vehicle and Mobility who earned his undergraduate degree at the Harbin Institute of Technology's School of Mechatronic Engineering. In under a year, the company closed angel, strategic, and Pre-A1 funding rounds, with investors including Yuanhe Puhua, Blue Lake Capital, and Oasis Capital, a pace of capital formation unusual even by the standards of China's crowded embodied-AI funding market this year, and one that reflects how urgently the sector's better-funded players have concluded they need a working answer to the data problem.
What NeuroScale Actually Captures
OriginFlow's answer is a data-collection paradigm it calls NeuroScale, built around a non-invasive neural-motor interface rather than a camera, glove, or exoskeleton. The company's OriginKit Gen 1.0 hardware is a wristband that reads surface electromyography, the electrical signal a muscle generates when it contracts, directly from the skin rather than tracking the hand's position after the fact. A self-developed model the company calls PULSE decodes that raw electrical signal into continuous hand posture, applied force, and tactile feedback data, information a camera-based system cannot recover because it never had access to the muscular signal that produced the motion in the first place.
The distinction between tracking a hand's position and reading the neural signal that commanded it is the core of OriginFlow's technical bet. A motion-capture system can tell a model where a fingertip ended up; it cannot tell the model how much force was behind the motion, whether the grip was tightening or already slipping, or how the hand adjusted mid-motion in response to an object's unexpected resistance, the kind of fine-grained feedback loop that separates a robot that can pick up an egg without crushing it from one that can only handle rigid, forgiving objects. By capturing the muscular signal directly, OriginFlow is attempting to recover exactly the force and contact information that has been the hardest category of data for the embodied-AI industry to collect at scale.
From Muscle Signal to "Human Token"
The company's stated ambition goes beyond collecting better hand data for its own sake. OriginFlow packages the decoded posture, force, and tactile information into what it calls Human Tokens, machine-learnable action representations designed to transfer across different robot embodiments rather than being tied to the specific hardware used to collect them. That framing borrows directly from how large language models treat text: a token is a unit of information a model can learn from regardless of which document it originally came from, and OriginFlow is betting that physical interaction data can be tokenized the same way, so that a grasping motion recorded on one wristband can train a robot hand built by an entirely different manufacturer.
Qin has framed the underlying problem in blunt terms: the real world, he has said, lacks a layer capable of abstracting complex physical interaction information into trainable representations, the same layer that text and image data already have through tokenization and embedding pipelines built over the past decade. If that gap is as fundamental as OriginFlow's pitch assumes, whichever company builds the first widely adopted abstraction layer for physical interaction data stands to become an infrastructure supplier to the entire embodied-AI industry, not merely a hardware vendor selling wristbands to individual robotics labs.
Why Investors Moved This Fast
The five-month, RMB 500 million (roughly US$69 million) funding pace requires context most coverage of the round has skipped past. China's embodied-AI sector has spent much of 2026 shifting its investment focus from robot hardware, where the market has grown crowded with dozens of humanoid manufacturers chasing similar specifications, toward the data and simulation infrastructure that determines how quickly any of those robots actually get useful. A data-collection company that can plausibly claim to serve every hardware manufacturer at once, rather than compete against them, is a structurally different investment thesis than backing another humanoid start-up, and it is the thesis several of China's most active robotics investors have concluded is underpriced relative to hardware.
That does not mean the thesis is proven. OriginFlow's own commercialization plan, industrial manufacturing partnerships with unnamed leading enterprises and a household-services data-collection partnership with 58 Group, is still in its early, deal-by-deal phase, and a data-infrastructure company's actual value depends entirely on whether enough robot manufacturers adopt its data format rather than build a competing pipeline of their own. Investors backing OriginFlow at this stage are underwriting the abstraction-layer thesis more than any current revenue figure, a bet on where the industry's bottleneck moves next rather than where it sits today.
The Adoption Problem Every Data-Infrastructure Bet Faces
The history of infrastructure layers in adjacent industries offers a useful caution here. A data format only becomes genuinely valuable once a critical mass of downstream users adopts it as a shared standard rather than as one vendor's proprietary tool, and that adoption threshold has killed more promising infrastructure companies than any technical shortfall. OriginFlow's Human Token format competes not just against rival sEMG or teleoperation data providers but against every humanoid manufacturer's incentive to keep its own training data proprietary rather than standardize on an external supplier's format, particularly once a manufacturer has invested in its own data pipeline.
Meta's own research into neural-interface wristbands for consumer augmented-reality control, built on a similar sEMG principle, is a reminder that OriginFlow is not alone in treating muscle-signal capture as a promising interface layer, though Meta's effort is aimed at human-computer interaction rather than robot training data, a different commercial target with a different adoption path. The more direct competitive pressure on OriginFlow comes from teleoperation-data companies and simulation-first data providers inside China's own embodied-AI sector, several of which have raised comparable or larger rounds this year on data-infrastructure theses of their own, meaning OriginFlow's window to establish Human Tokens as a shared industry format, rather than one proprietary option among several, may be narrower than its funding pace suggests.
The Data-Ownership Question Underneath the Pitch
OriginFlow's model also raises a question that every buyer of embodied-AI training data eventually has to confront, one that predates this specific company and will outlast it: who owns the data generated when a human wears a company's wristband to perform a task, and what rights does that company retain over the resulting Human Tokens once they are sold or licensed to a robot manufacturer. That is the data ownership question that every integrator will face as physical-interaction datasets become a tradeable commercial asset rather than a byproduct collected internally, and OriginFlow's public materials so far describe its collection methodology in more detail than its data-rights and licensing terms, an imbalance common across the sector but one that will matter more as the company's household-services partnership with 58 Group begins collecting data inside people's homes rather than inside a factory.
The household-services application is, in fact, the more commercially and ethically complex half of OriginFlow's roadmap. Industrial-manufacturing data collection happens on a company's own premises under existing workplace consent frameworks; home-services data collection, capturing how a person performs cleaning, cooking, or caregiving tasks so a robot can eventually learn the same motions, involves recording activity inside private homes, a context where consent, data retention, and re-identification risk carry materially higher stakes than a factory floor. How OriginFlow and 58 Group structure that partnership's consent and data-handling terms will likely shape how comfortable other household-robotics companies are partnering with sEMG-based data collectors going forward.
What Would Prove the Thesis Right
The clearest signal that OriginFlow's abstraction-layer bet is working will not be another funding round but a named robot manufacturer, ideally one that does not already have an equity or partnership relationship with OriginFlow, publicly adopting Human Tokens as a training input for a commercial product. Until that happens, the round is evidence that investors find the thesis compelling, not evidence that the market has settled on OriginFlow's format over a rival's. The distinction matters for anyone weighing this story less as a funding headline and more as a signal about where embodied-AI's actual constraint is moving.
The next twelve months will show which of the sector's competing bets on the data bottleneck was right: whether the constraint on robot manipulation was hardware precision, model architecture, or, as OriginFlow argues, a missing layer for abstracting physical interaction data the way language models abstract text. If Qin Shentao's framing holds, the company that owns the token format other robots learn from could end up mattering more to the industry's trajectory than any single humanoid manufacturer showing off a new demo this week, a possibility worth watching regardless of how OriginFlow's own commercial roadmap unfolds from here.
Disclaimer: This article is for general information purposes only and does not constitute investment, legal, or professional advice. Readers should verify details with primary sources before making business decisions.